Programming & Data Handling
- Python
- Pandas
- NumPy
- Matplotlib
- Seaborn
Tiyyagura Chandra Reddy
I build machine learning pipelines, predictive analytics, and data engineering systems that turn complex data into practical business outcomes.
Software engineering & data
Software Engineer · AI/ML & Data
Data pipelines to deployment
As a Data Scientist and AI/ML Engineer with over 3+ years of software engineering experience, I specialize in developing end-to-end machine learning solutions that drive business value. Currently leading a team of 4 at HCLTech, working with Adobe to create innovative solutions that enhance user engagement and drive conversion rates.
My expertise spans the entire ML pipeline - from data preprocessing and feature engineering to model deployment and monitoring. I'm passionate about leveraging cutting-edge technologies like LangChain, RAG systems, and Generative AI to solve complex business problems.
Building predictive models, implementing deep learning solutions, and deploying ML pipelines
Working with transformers, BERT, GPT models, and developing conversational AI systems
LLMs, RAG systems, prompt engineering, and building AI-powered applications
AWS deployment, containerization with Docker, and CI/CD for ML models
Technical toolkit
Selected work
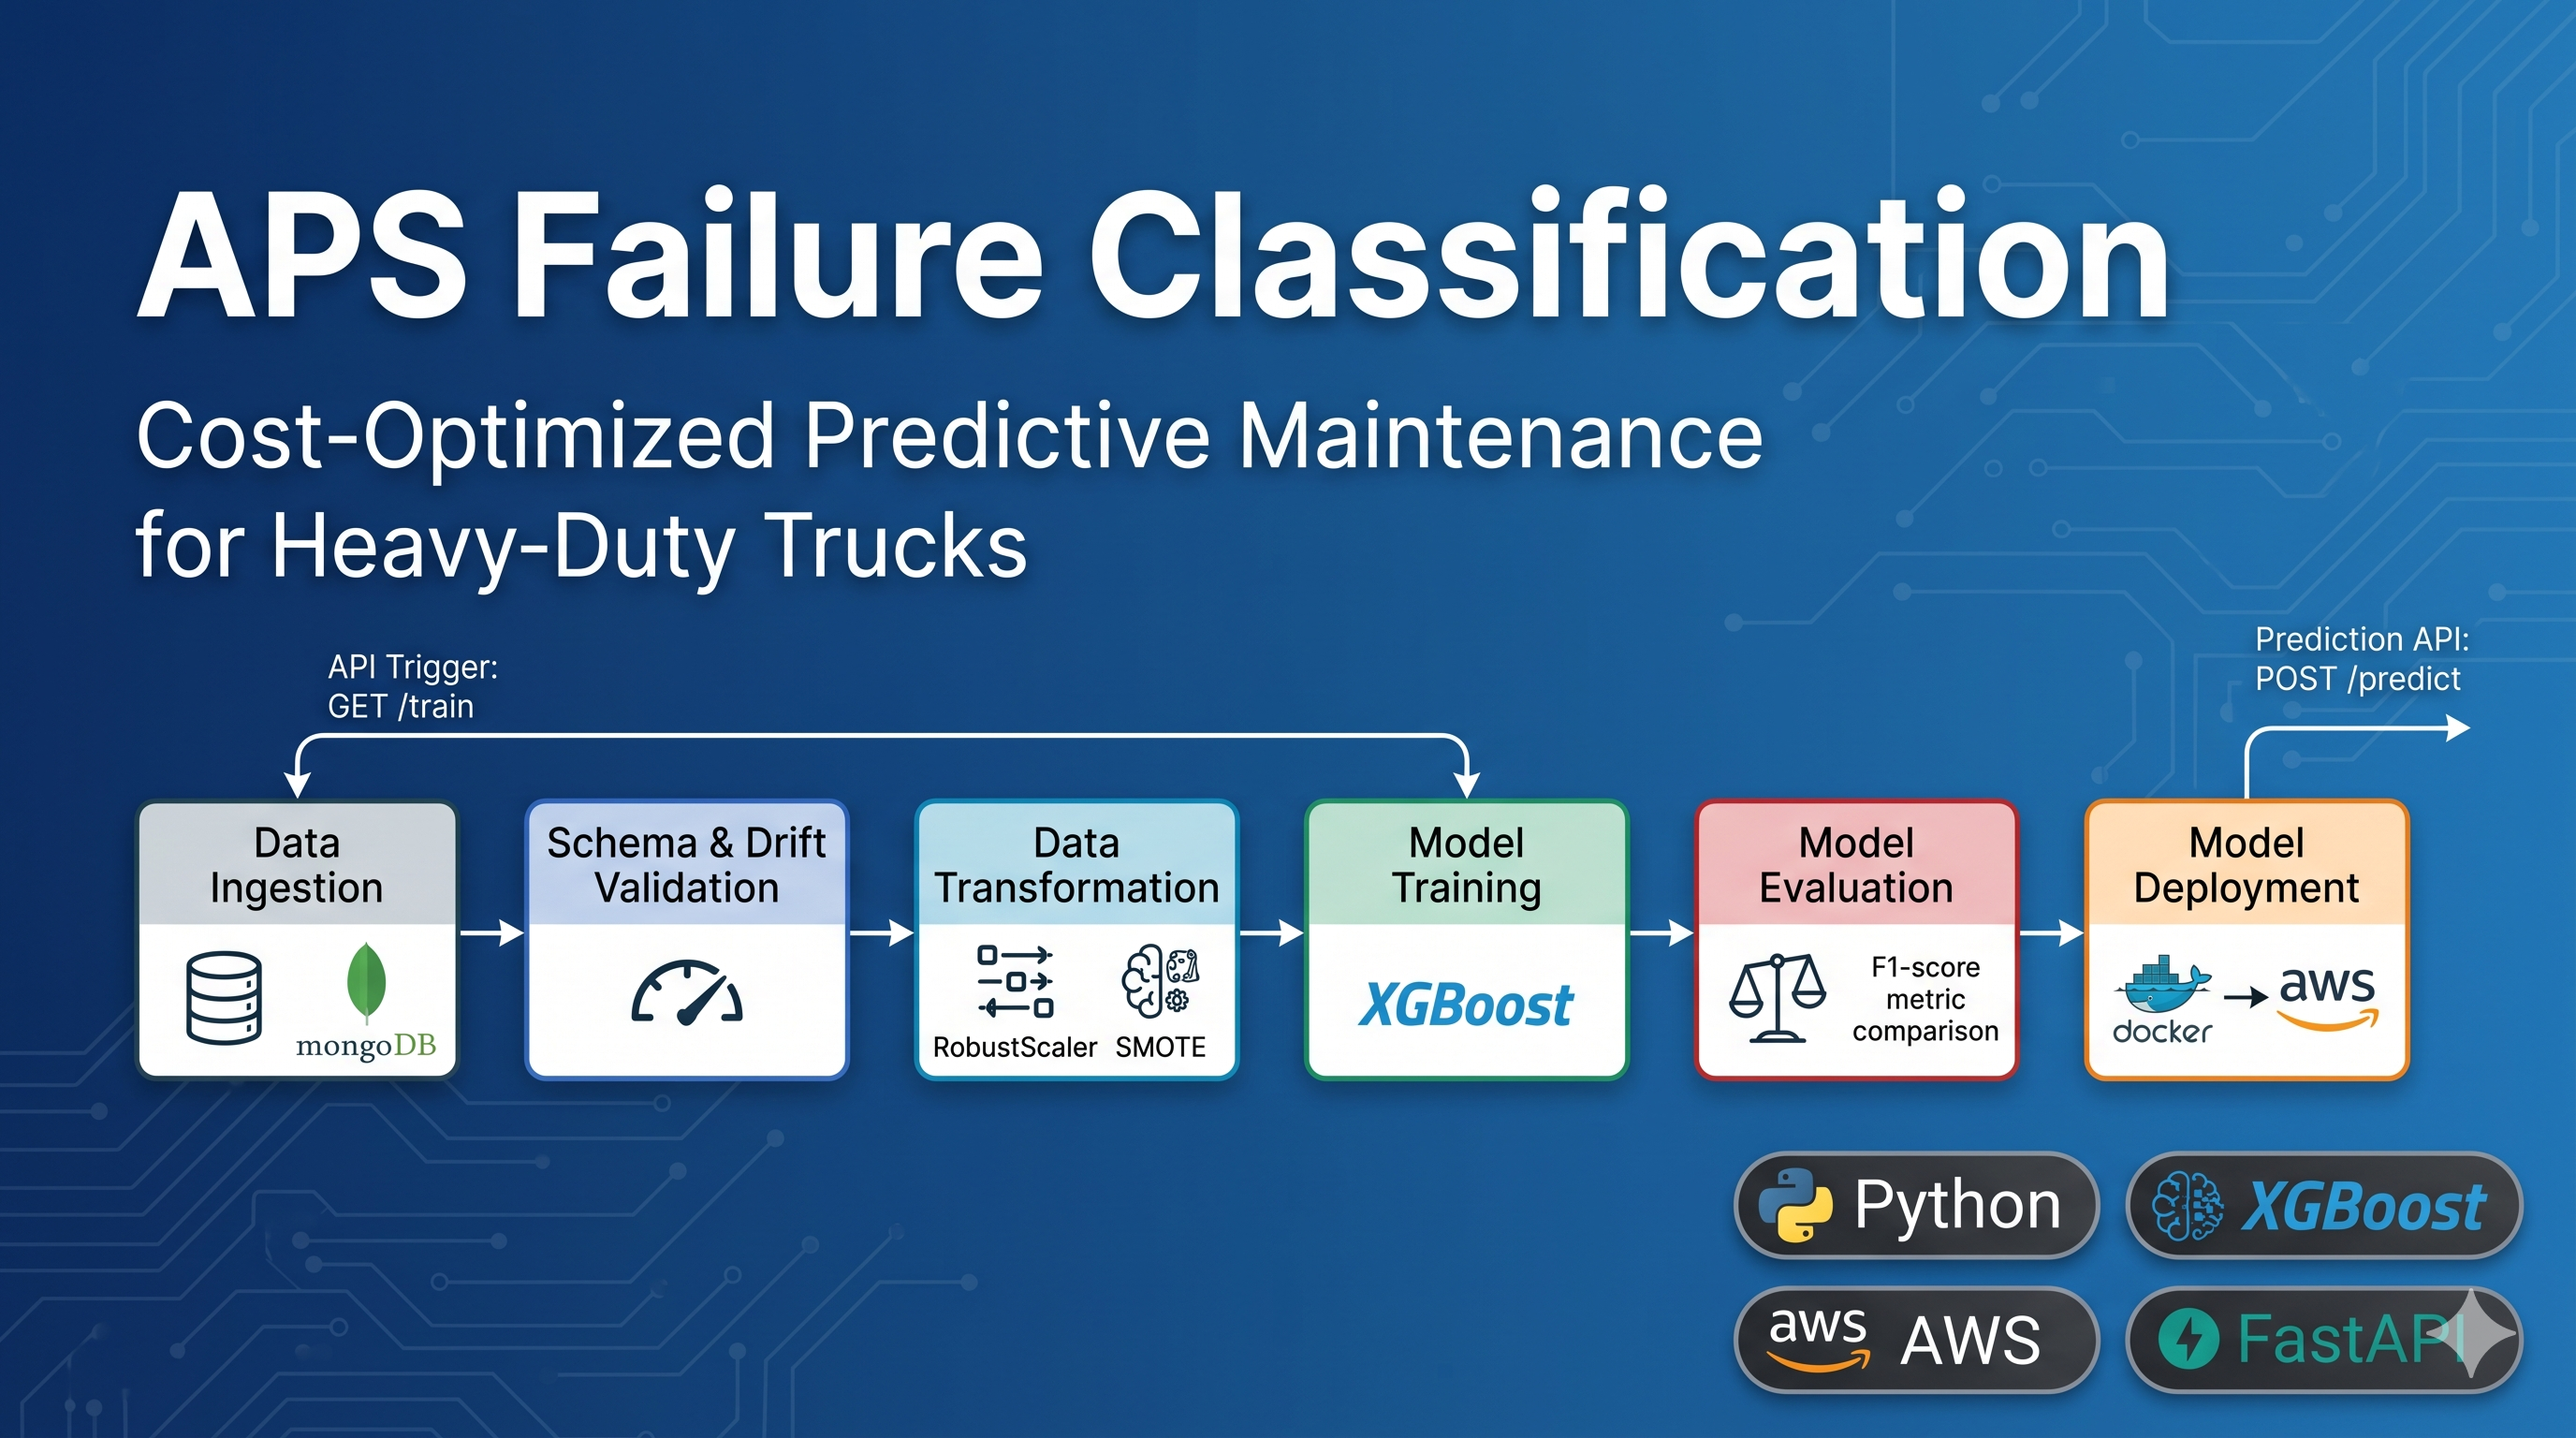
An end-to-end predictive maintenance pipeline for Scania trucks, built around the asymmetric cost of missed failures.
Read case study ↗
Classifying financial product complaints to help teams identify problems and prioritize customer support.
Read case study ↗HCLTech · Bengaluru · Nov 2022–Present
Building AI/ML pipelines, predictive analytics, and data-driven campaign strategies at enterprise scale.
Reported impact: 40% increase in legitimate license upgrades, with telemetry pipelines processing millions of machine IPs and license logs.
Built automated ML pipelines to ingest and process high-volume telemetry data from the Genuine Integrity Service, identifying non-genuine user cohorts with high accuracy across millions of machine IPs and license logs.
Designed and deployed predictive targeting workflows using classification models to segment non-genuine users, enabling personalized discount campaigns and automated software disablement triggers — directly impacting revenue recovery.
Architected and ran A/B testing frameworks to optimize the conversion funnel; introduced a strategic 7-day grace period that significantly increased legitimate license upgrades by converting at-risk users.
Built production-grade data pipelines with PySpark and AWS (S3, EC2, ECR), achieving low-latency synchronization between client-side detection services and backend campaign execution systems.
Python, PySpark, Machine Learning, AWS S3, AWS EC2, AWS ECR, A/B Testing, Data Pipelines, Classification Models, Telemetry Analytics, AEM, MILO, AJO, Figma, Jira
LBRCE · Jun 2018–May 2022 · CGPA 8.95
A strong foundation in algorithms, data structures, and software development.
Computer science fundamentals, software engineering, database systems, web development, project management, machine learning, deep learning and NLP, exploratory data analysis, and big data.